 OpenAdapt
 learns a task, then runs it as a program
A person or agent shows OpenAdapt a data-entry task, which becomes a program that repeats the steps with new details. A person approves each entry until the workflow has proved itself. You can then have it ask only about problems. After each save it reads the record back, or says so when it can't. It stops when something doesn't match.
Updated 2026-11-19
Show it once. Run it every time.
One harness, three modes. A model works only while a task is shown or repaired, on your own key.
- 01 Explore
Show the task once
Your agent or a person does the task while OpenAdapt records every action. The save is read back before anything compiles.
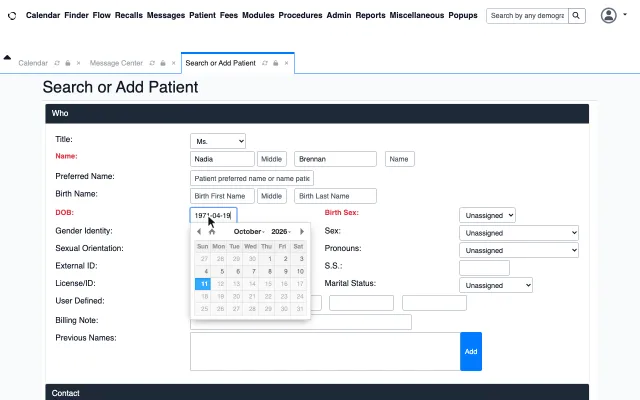
- clickTitle
- typeMs.
- clickFirst name
- typeNadia
- clickLast name
- typeBrennan
- 02 Run
The program repeats it
New inputs, the same compiled steps, no model calls. It confirms the record before each save and reads it back after.
Chart read back · 12 of 12 match
- Title
- Ms.
- First name
- Nadia
- Last name
- Brennan
- Date of birth
- 1971-04-19
- Sex
- Female
- Street
- 27 WILLOW BEND ROAD
- City
- EXAMPLETON
- State
- MA
- Postal code
- 02139
- Home phone
- 555-0121
- nadia.brennan@example.invalid
- Country
- USA
- 03 Repair
When the app changes
The run stops before saving. An agent shows the fix, the program tries it up to the save without saving, and a person approves it.
Nothing saved until a person approves
- The run stops before the save.
- An agent shows the fix on your own key.
- The program replays it up to the save, without saving.
- A person approves the new version, which can be rolled back.
Try the method here
Fill in the form once, run the program on 25 referrals, then change the app and see what it does.
- 1Show the task
- 2It becomes a program
- 3Run it on 25
- 4Change the app
Each action you take becomes a step here.
Type in the form, or tap Fill example.
An interactive demo with synthetic records. It runs in your browser and sends nothing.
How it works, in detail
OpenAdapt needs to see a data-entry task done once, by a person or an AI agent. It turns that run into a program that makes the same entry on later runs without calling an AI model. The program confirms the right record before each save, reads the record back after it, and stops and asks a person when something doesn't match.
A person or an agent shows the task
A person or an AI agent does the task once on a test record. When a person shows it, OpenAdapt records the screen and every click and keystroke. On this site, a test script stood in for that person.
A computer-use agent can show the task instead: OpenAdapt turns the agent's successful run into the same kind of program, so later entries make no model calls. A person accepts the program before it runs. How to set it up.
You can also give it several demonstrations. OpenAdapt compares them to find which values change, which steps repeat and which are optional. If they don't agree on what the task is, it says so and builds nothing. It can also fill a task's inputs from a referral PDF, a fax image or an email.
Who approves each entry
By default, every save waits for a person's approval, on the computer or on a paired phone. Look-ups that save nothing need none.
After a readiness test, if OpenAdapt can read saved records from your system's data, a workflow can ask a person only about problems. Repeated problems switch it back. A person can also sign a grant that lets a named system or agent answer saves; the result says who approved.
When something doesn't match, it stops and asks
There are two kinds of stop; the result says which.
It stops before saving
In our 2026-10-12 claims test, one claim had a mistyped insured number. openIMIS found no member, so the screen no longer matched the demonstration, and the program stopped before saving. No claim was written: Stopped before saving.
It stops after saving started
In our 2026-10-11 referral test, the referral said Rosa Delgado, born 1958-03-22. The EMR's duplicate check found a Rosa Delgado born 1958-03-27. The program stopped before confirming and flagged Check the record for a person. A separate read afterwards found no new chart.
What a stop doesn't do: the claims program stopped because openIMIS found no member, not because it compared the number with the document. If a mistyped number had belonged to another member, the screen would have looked normal, and only a record check or a person would catch it.
How every entry ends
Every entry ends with one plain result. It says "nothing was written" only when the run proves it.
| Result | What it means |
|---|---|
| Done and checked | Saved, then read back from the system's own data, and every field matched. |
| Stopped before saving | It stopped before changing anything and asked a person. Nothing was written, and the run proves it. |
| Check the record | It had started saving, so it can't promise nothing was stored. A person checks the record before anything is tried again. It never retries on its own. |
| Finished, not checked | It did the steps but didn't confirm the saved result. Practice runs and programs with no record check are always labeled this way. |
| Didn't finish | It couldn't complete the task. The result says what is known about whether anything was written. |
It reads the saved record back
After saving, OpenAdapt reads the record back another way, such as a report export, read-only API access or a database read, and compares the fields it typed. That catches a wrong field or record, a missed keystroke, or a step that ran too early. Re-reading the screen it typed on doesn't count: that shows what was typed, not what was stored. A run with no second way to read ends Finished, not checked, and we won't approve such a workflow to save entries on its own.
Why a separate read matters: in our fault test, 72 of 90 runs left the record wrong. A check of the screen's "Saved" message alone passed 54 of those 72. A read over the app's API missed 9; the full database read caught all 72. These were faults we injected on a test system: a coverage test, not a real-world error rate. More in How do you know an automation saved the record?.
It checks it's the right record
Before it types into a record, it confirms it's the right record, and stops when it isn't sure. In our look-alike test set (same name, same birth date, record numbers like MG4408 and MG44O8), it stopped on 5 of 5 look-alike patients. More on the right-record check.
Its limits: the check covers the steps that carry a patient's identity. On pixel-only screens, such as remote desktop, it stops whenever the right patient's own record number has look-alike characters: 47 to 61 in 100 correct-patient checks on our test corpora (re-measured 17 Oct 2026). A confirmed list of the system's record numbers removes most of those stops. Extra stops, not wrong entries.
When the screen changes, it finds the field or stops
A recorded macro keeps clicking where a field used to be. OpenAdapt finds the field again by the page's structure, its label, its picture or nearby text, or stops. On Frappe Lending, after a cosmetic screen change, 3 of 3 runs found the fields again and were checked. Over remote desktop, 3 of 3 runs on a changed screen stopped. A fix ships as a new, tested version of the program, staged before it's used and possible to roll back.
Where it runs
It runs on a computer or virtual machine you control, signed in to your system. That computer keeps each run's full record. It works in web apps, native Windows and macOS apps, and over remote desktop. Security and the data map.
What your IT team does, once
- Sets up one computer or virtual machine, signed in to the system.
- Installs the open-source engine with us and allows it to control the keyboard and mouse.
- Creates a read-only login, so OpenAdapt can look each saved record up and check it.
What we've tested
Every run below used synthetic records on open-source software or our own test apps. We qualify each workflow on your own system before it touches a real record. All tested runs.
| System | Task | Result | Date |
|---|---|---|---|
| OpenEMR 8.0.0.3, open-source EMR, browser | Register a referred patient, timed against an AI agent | 62 of 63 saved correctly, same as the agent; 9 of 9 possible duplicates created no chart | Oct 2026 |
| MockMed, our synthetic clinic app | Add a note; then the same with the save rejected | Done and checked; with the save rejected, it stopped (Check the record) | Oct 2026 |
| openIMIS 25.10, open-source insurance system, browser | Enter a claim, 150 claims | 148 of 149 saved correctly by read-back; 0 saved wrong without a stop | Oct 2026 |
| openIMIS 25.10, browser | Enter a claim, 6 claims, filmed | 5 saved, 15 of 15 fields read back by our test setup; 1 stopped before saving | Oct 2026 |
| openIMIS 25.10, browser | Eligibility look-ups | 3 of 3 active confirmed; 3 of 3 expired stopped | Jul 2026 |
| Our scheduling app over real remote desktop | Book an appointment | 3 of 3 confirmed; 3 of 3 wrong-patient runs stopped | Jul 2026 |
| Frappe Lending, open source | Loan application after a screen change | 3 of 3 found the fields and were checked | Jul 2026 |
| Our own Windows test app | A form task | 3 of 3 confirmed by a database read | Jul 2026 |
What you get
- A program for one task in one system, built with you and tested on test records.
- A plain result for each entry: Done and checked, Stopped before saving, Check the record, or Finished, not checked.
- A receipt for each entry that ends Done and checked (the result and each check it ran, without patient details), and a full run record of every entry on your computer.
- For upkeep, you get a tested fix when your system changes, and your staff approve it before it's used.
OpenAdapt is built to run in production, where admissions are signed and the record is checked whenever a program saves. It runs locally or in your VPC, and the Enterprise plan includes a BAA. Before it touches a real record, we qualify it on your system against your normal and fault cases. Pricing
The parts, for engineers
The open-source engine is openadapt-flow. It compiles a recorded demonstration into a program and runs it with checks of the record before typing and after saving. It also runs a program over a worklist, fills a workflow's inputs from a referral PDF, fax image or email, turns an AI agent's successful run into a program, and lets your AI agent hand it entries to make and check. The rest of the platform builds on it.
Sources
- Referral timing run, local OpenEMR 8.0.0.3 test copy, 14 to 15 Oct 2026 (run data): 8 synthetic referrals, OpenAdapt (a program compiled to find each field by the page's structure, 0 model calls) against Claude Sonnet 5.5 (claude-sonnet-5-5) as a computer-use agent in a capped harness, warm starts, interleaved blocks, each chart read back from the database. Blocks 2 to 10, normal referrals saved correctly: 62 runs each; median 29.7 s (OpenAdapt) and 36.5 s (agent); agent median $0.083 a run at list price. Both 62 of 63 normal referrals correct; on the possible duplicate, no new chart in 9 of 9 for both. Block 1 left out (CPU shared with another process); with it (blocks 1 to 10), 69 of 70 correct for both, 29.7 s and 37.6 s (n=69 each). The same task from the 10 Oct recording without the page's structure: 62 of 63, 38.6 s median, slower than the agent.
- OpenAdapt on OpenEMR 8.0.0.3 (open-source EMR), local test copy, 11 Oct 2026. One program ran over 8 synthetic eReferrals in one batch, with 0 AI model calls. 7 new patients were saved; our test setup read each chart back through the OpenEMR API and database, and 12 of 12 fields matched the referral. The 8th (Rosa Delgado, same name as an existing chart, different birth date) stopped at the EMR's duplicate check; afterwards no new chart existed. The engine labels the saved runs "Finished, not checked" (practice profile) and the stop "Check the record".
- OpenAdapt scoreboard, openIMIS 25.10 (open-source insurance system; it runs Nepal's national health insurance scheme), local test copy, Oct 2026 (SCOREBOARD.md): a compiled program, 0 AI model calls, entered 150 synthetic claims. 148 of 149 were saved correctly, checked by reading each claim back; 0 were saved wrong without a stop; the claim with an injected screen change stopped.
- OpenAdapt on openIMIS 25.10 (open-source insurance system), local test copy, 12 Oct 2026. A program learned from one demonstration entered 6 synthetic health-facility claims in one batch, with 0 AI model calls. 5 were saved; our test setup read each back through SQL and the openIMIS API, and 15 of 15 fields matched the claim document. On the 6th, the insured number had two digits swapped: openIMIS found no member, the screen no longer matched the demonstration, and the program stopped before saving (no claim was written). The engine labels the 5 saved runs "Finished, not checked", because this program has no record check of its own yet.
- OpenAdapt on openIMIS 25.10 (open-source insurance system, not a US payer portal), July 2026, synthetic members: 3 of 3 active policies confirmed, 3 of 3 expired policies stopped, 0 active policies stopped by mistake. Checked by a read-only database query of the policy, product and dates.
- OpenAdapt remote-desktop test, 30 Jul 2026: a fictional clinic scheduling app over a real remote-desktop connection (FreeRDP, not Citrix), synthetic patients. 3 of 3 bookings confirmed by a read-only database query; 3 of 3 wrong-patient runs stopped with 0 rows written; 3 of 3 runs on a changed screen stopped. 0 AI model calls.
- OpenAdapt look-alike test set (synthetic rows), 2026: 5 of 5 look-alike patients stopped; of the 2 control cases, the right patient was let through and a plainly different patient was stopped. On pixel-only screens the check stops whenever the right patient's own record number has look-alike characters (O and 0, l and 1); on our test corpora that was 47 to 61 in 100 correct-patient checks, re-measured 17 Oct 2026 (IDENTITY_EVIDENCE.md). With a confirmed list of the system's record numbers (openadapt-flow 2.2.0), those stops on a rendered record list fell from 176 to 3 in 280 clicks whose neighboring row wasn't a look-alike twin (KNOWN_IDS.md).
- OpenAdapt on Frappe Lending 16.2.0 (open source), 16 Jul 2026, synthetic applicants: 6 of 6 loan applications checked through the API, a database read and a table-change audit (3 normal runs, 3 after a cosmetic screen change); 5 of 5 injected faults stopped before saving.
- OpenAdapt on our own Windows test app (UI Automation), 17 Jul 2026: 3 of 3 runs with saves confirmed by a database read; missing and ambiguous targets refused 3 of 3.
- OpenAdapt fault test, openadapt-flow benchmark/effect_e2e, 2026: faults injected into our own engine on a test record system, 90 runs; 72 left the record wrong. A check of the screen alone passed 54 of those 72; a read-back over the app's REST API passed 9 of them; the full database read caught all 72. A coverage test over a fixed fault list, not a real-world error rate.
See it on your process
Bring a task your team types every day. We'll tell you whether it fits and what a test on your own system would cover.